

Best Mini PC for Local LLMs
Which local LLM fits on a Mini PC (via Ollama, LM Studio, or llama.cpp) is a RAM capacity question first. At 4-bit quantization (Q4_K_M), an 8B model wants about 6GB–8GB plus room for the OS and context window, making 16GB of RAM the practical floor. A 32B model (or Mixture-of-Experts coding models in that weight class) wants roughly 20GB–24GB and is much happier at 32GB. A 70B model needs 48GB or more, which is why 64GB Mini PCs are the ones homelabbers shop for when running large models locally. Because Mini PCs use unified system memory shared between the CPU and integrated GPU, your system RAM is your VRAM pool.
Once a model fits in memory, memory bandwidth (DDR5 dual-channel or LPDDR5X) and a stronger integrated GPU (such as AMD’s Radeon 780M or 890M with ROCm/Vulkan acceleration) determine how quickly prompt processing and token generation run. The picks below state which of 8B, 32B, and 70B each configuration can hold, with nothing under 16GB included in the pool.
Current picks
-
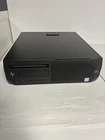
1. Budget entry for 8B models
HP Z2 G4 SFF
$175Pre-OwnedSFFIntel Core i7-870016 GB1000 GB HDDFits 8BAt $175, this setup provides 16GB of RAM, which is enough memory to fit an 8B model at 4-bit with room left for the operating system. It does not fit 32B or 70B models, and its integrated graphics are weak, meaning execution will still be slow. It is an affordable way to start experimenting locally.
-

2. Balanced graphics for 8B models
KAMRUI (Ryzen 7 7735HS)
$376.61AMD Ryzen 7 7735HS16 GB512 GB SSDFits 8BPriced at $376.61 as of November 22, 2026, this unit pairs 16GB of memory with mid-tier Radeon 680M integrated graphics. It fits an 8B model at 4-bit alongside the OS, though it cannot fit 32B or 70B models. The stronger graphics provide a solid option when you want better speed for standard 8B workloads.
-
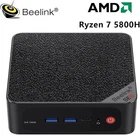
3. 32GB capacity for larger models
Beelink SER5 Max
$439.95Very Good - RefurbishedAMD Ryzen 7 5800H32 GB1000 GB SSDFits 32BFor $439.95, this machine packs 32GB of RAM, enabling it to fit both 8B and 32B models quantized to 4-bit. While it cannot fit 70B models and relies on weak integrated graphics, the expanded memory gives you the headroom needed for larger parameter sizes.